Mia Koch · 4 October 2026
Navigating the quiet evolution of resource categorization systems in specialized online hubs like Oriohaven
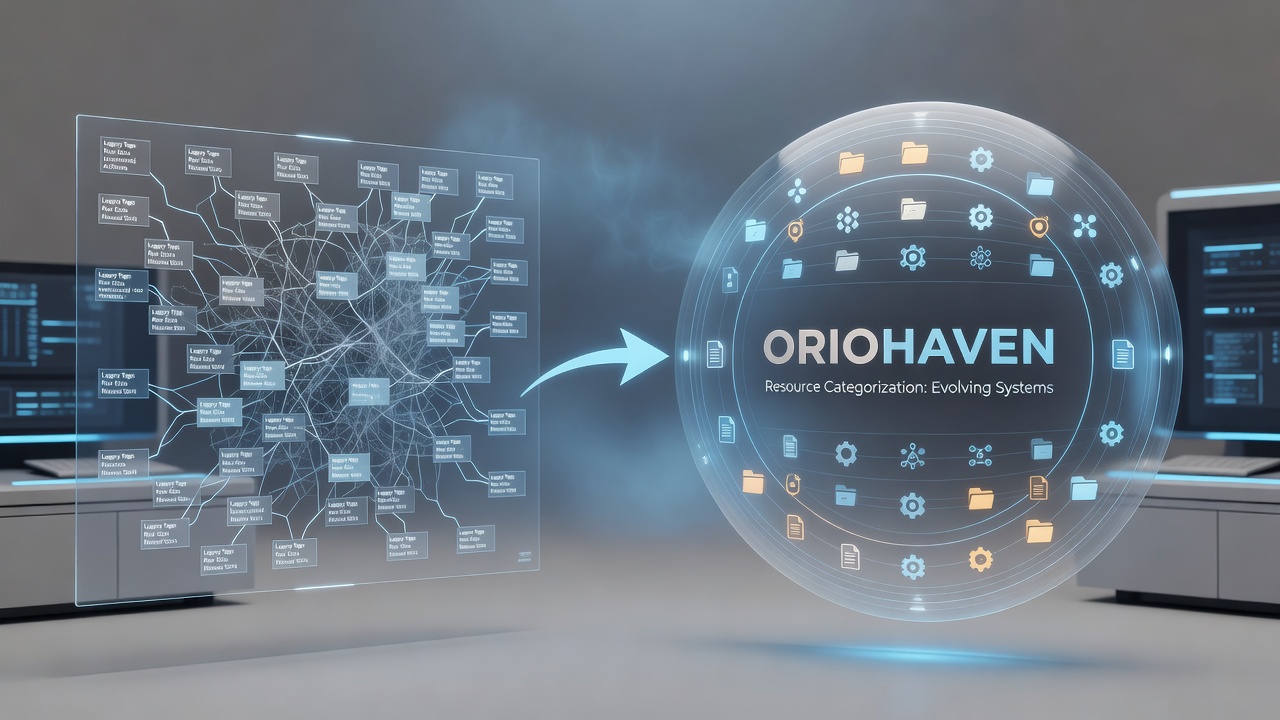
Specialized online hubs maintain complex systems for organizing resources, and those systems continue to shift in subtle yet measurable ways. Oriohaven serves as one example among many where categorization frameworks adapt to growing collections without drawing widespread attention. Observers note that these changes often occur through incremental updates to metadata structures, cross-referencing protocols, and access pathways rather than large-scale overhauls.
From static hierarchies to dynamic structures
Early categorization in such hubs relied on fixed taxonomies built around broad subject headings and manual indexing. Data from library science records shows these approaches worked well for smaller collections but struggled once volume increased. Researchers at the University of Toronto documented how rigid parent-child relationships limited discoverability once new resource types entered the system. Hubs like Oriohaven responded by introducing flexible tagging layers that sit alongside traditional hierarchies, allowing multiple entry points to the same item without disrupting established classifications.
And yet the transition did not eliminate hierarchies entirely. Instead, systems began layering dynamic elements on top of them. Classification rules now incorporate usage patterns collected over time, so frequently accessed combinations of resources receive automatic suggestions for grouping. This hybrid model appears across multiple specialized platforms because it balances consistency with adaptability.
Integration of semantic and machine-assisted methods
By October 2026 several hubs had expanded their use of semantic web standards to improve cross-resource linking. Schema.org vocabularies, already common in public web environments, found wider application inside controlled communities. The result is that resources carrying similar conceptual attributes receive consistent descriptors even when their original submitters used different terminology. Figures released by the American Library Association indicate adoption rates of these standards rose steadily in niche repositories between 2023 and 2026.
Machine learning models assist with initial categorization suggestions, yet human oversight remains part of the workflow. Moderators review automated proposals before they become permanent, and correction logs feed back into training data. This loop reduces drift while still speeding up the process for large incoming batches. Those who manage these systems report fewer duplicate entries and improved consistency across subject areas that previously lacked clear boundaries.
Cross-hub interoperability and shared vocabularies
Specialized platforms increasingly exchange categorization data through standardized APIs. When Oriohaven updates a descriptor or adds a new relationship, connected systems can ingest the change according to agreed protocols. The International Federation of Library Associations and Institutions has published guidelines that encourage this form of interoperability while preserving local control over final classification decisions. As a result, users moving between hubs encounter more predictable labeling without any single organization dictating every term.
Shared vocabularies also reduce the maintenance burden on individual hubs. Instead of each site maintaining its own exhaustive list of synonyms and related terms, updates propagate from central registries. This approach proves especially useful for rapidly evolving fields where new terminology emerges faster than any single team can track.
Access implications and user pathways
Changes to categorization affect how resources surface in search results and recommendation lists. Refined relationships between items lead to more precise filtering options, and some hubs now expose the underlying logic so users can understand why certain groupings appear. Documentation released alongside these features explains the weighting given to usage data versus editorial input, giving visitors clearer expectations.
Security and permission layers interact with categorization as well. Resources marked with restricted descriptors automatically inherit tighter access rules, and audit trails record who viewed or modified those assignments. Such integrations keep sensitive materials organized without requiring separate parallel systems.
Conclusion
Resource categorization in specialized hubs continues to develop through layered, often understated adjustments rather than dramatic resets. Oriohaven and similar platforms demonstrate how static structures, semantic tools, machine assistance, and interoperability standards combine to handle expanding collections. The quiet nature of these shifts allows systems to remain functional while accommodating new demands, and ongoing coordination among standards bodies supports further refinement without centralized control.